Ingestion lifecycle
Follow governed knowledge from source discovery through immutable revisions and searchable projections.
Ingestion turns source content into governed Knowledge. Connectors and direct uploads enter through different trust boundaries, then converge on one immutable ledger and one publication model.
Search, vector, and graph records are outputs of this process. They are never the source of truth.
Ingestion flow
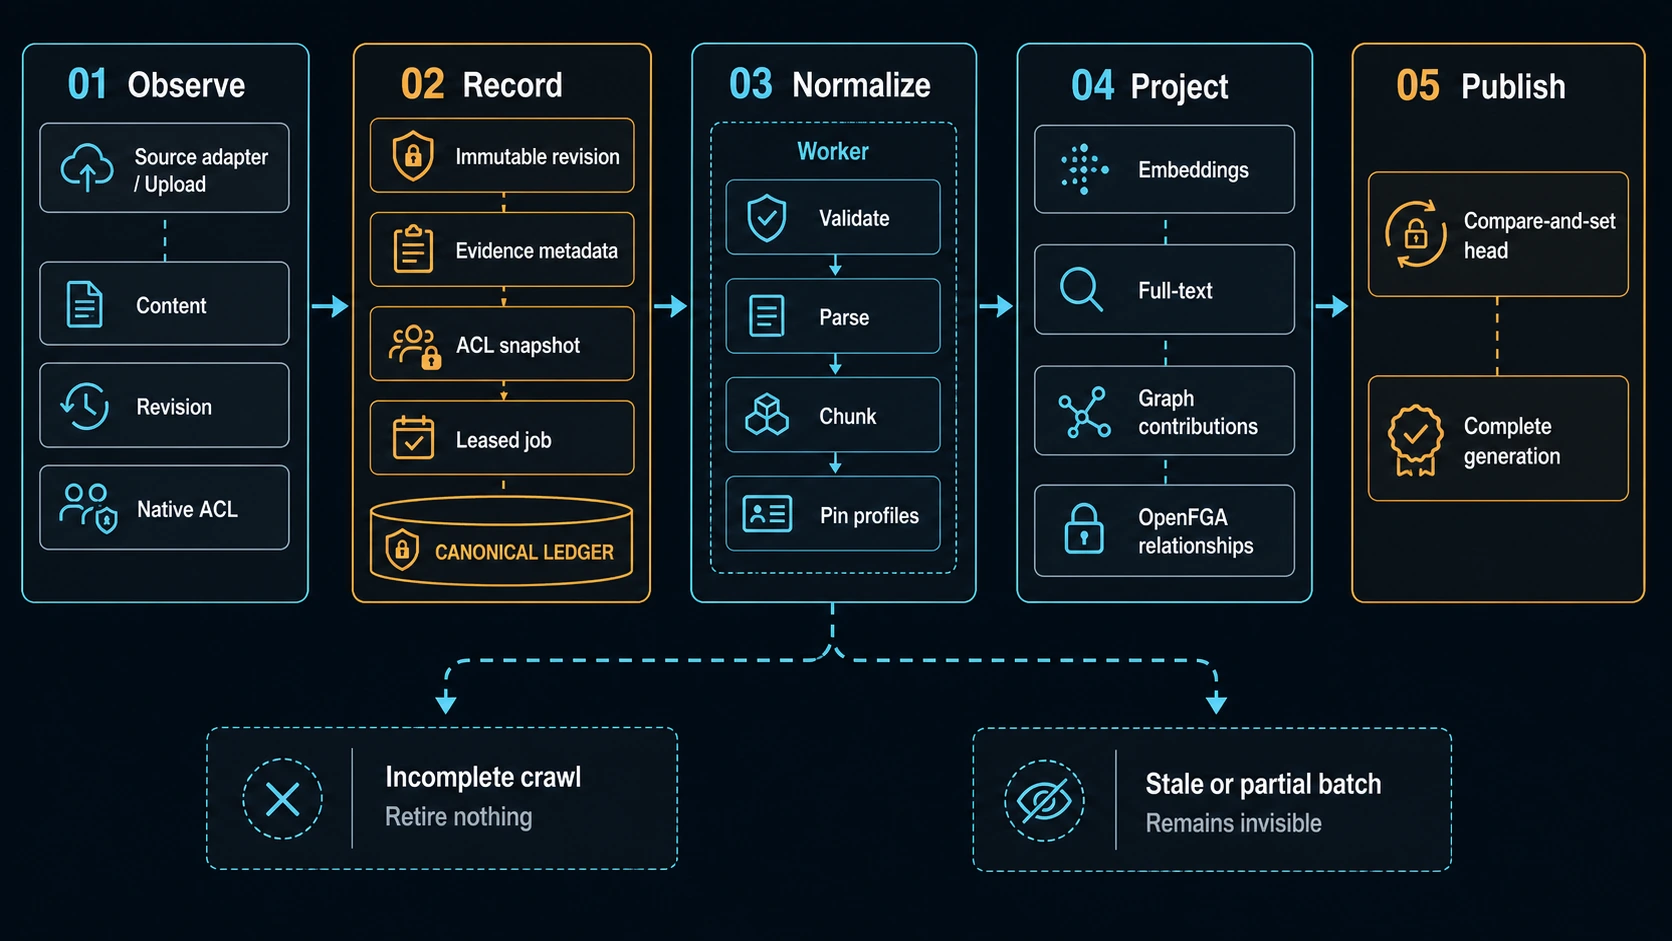
The lifecycle has five stages:
- Observe: accept a versioned connector batch or an authorized direct upload and record whether the supplied evidence is complete.
- Record: append an immutable source revision and retain the original bytes in object storage.
- Govern: resolve source identities, seal permission evidence, and apply the Organizational AI Memory classification ceiling — the sensitivity policy that can narrow, but never widen, source permissions.
- Process: validate and parse content, create chunks and embeddings, and extract graph contributions under pinned processing profiles.
- Publish: advance the current head with compare-and-set only when the version and projection generation are still current. Compare-and-set means the worker may replace only the head it originally checked.
Inputs
Connector batches
A connector sends one versioned crawl envelope for a source connection and
Knowledge Space. sourceSystem appears once on that envelope. Content,
identity, membership, and permission payloads have independent versions and
component checkpoints. Unknown versions fail closed.
Objects carry source-native IDs and revision markers. Permission entries use stable native principal IDs; email and display name are aliases, not authorization keys.
Connectors cannot choose ACL authority. Every connector profile is
source-authoritative, and the ledger records the object as SOURCE when it is
first ingested. If an adapter cannot establish an object's permissions, it
omits the object. It must not replace missing evidence with an empty grant list,
because a sealed empty ACL means the source granted nobody.
Direct uploads
The API first verifies can_create_asset on the target Knowledge Space. It
retains that Space identity through the source ledger and records the object as
ORGMEMORY-authoritative.
New versions remain inactive until required OpenFGA relationships and the publication head are confirmed. Later access is governed by the application-managed relationships and classification rules described in Authorization.
Permission evidence
Content and permission evidence change independently. A new ACL is appended as a sealed generation: an immutable, numbered permission snapshot. An existing sealed generation cannot be edited.
Membership is sealed separately. Removing someone from a source group can revoke their next request without rewriting content, rotating the object's group ACL, rechunking, or re-embedding.
An unmapped source principal grants nothing. Automatic identity mapping requires either an SSO-verified identity or an administrator's trust attestation for that connection.
Connector ACL generations expire 23 hours after capture. If a connector stops refreshing them, the affected content becomes unreadable instead of remaining visible under stale permissions.
Checkpoints and retries
The worker reloads enabled connection configuration and encrypted credentials on every poll, so configuration changes apply without restarting it.
Content, permissions, and membership keep separate observed and successfully reconciled checkpoints:
- an invalid envelope or unsupported payload version rejects the whole pending batch and records it as observed without advancing successful reconciliation;
- a failure for one connector object leaves that component pending for retry;
- after restart, another worker resumes from the recorded component checkpoints;
- a permanent direct-upload processing failure follows the upload quarantine path instead of the connector retry path.
Workers claim ingestion and graph jobs with leases. A graph job pins the Knowledge Asset version, source revision, target projection generation, and immutable graph-processing profile. The current ACL generation, active chunks, and embedding profile are resolved when the worker claims the job and are rechecked before publication.
Publication and deletion
Full-text, vector, and graph data become visible only through a current publication head. Contributions and embeddings publish atomically after a current-version check.
| Condition | Result |
|---|---|
| Processing or publication fails | The previous generation remains available; if none exists, the new content remains invisible |
| A job targets a stale version | The job is superseded and cannot become current |
| A complete crawl omits an old object | Reconciliation may retire it because the source declared the crawl exhaustive |
| An incomplete crawl omits an object | Nothing is retired merely because it was not observed |
| A source sends a tombstone | The object is archived out of retrieval and cannot be revived by a later content revision |
PostgreSQL remains the canonical ledger for revisions, sealed ACL evidence, checkpoints, jobs, and publication heads. Object storage retains immutable bytes. Search, vector, and graph records can be recreated from that evidence, although the product does not currently expose one full-rebuild command.
Last updated on